Writing Kernels Explained for Engineers
A four-step loop of draft, critique, vote, and recurse produces verifiable content at scale.
October 13, 2026
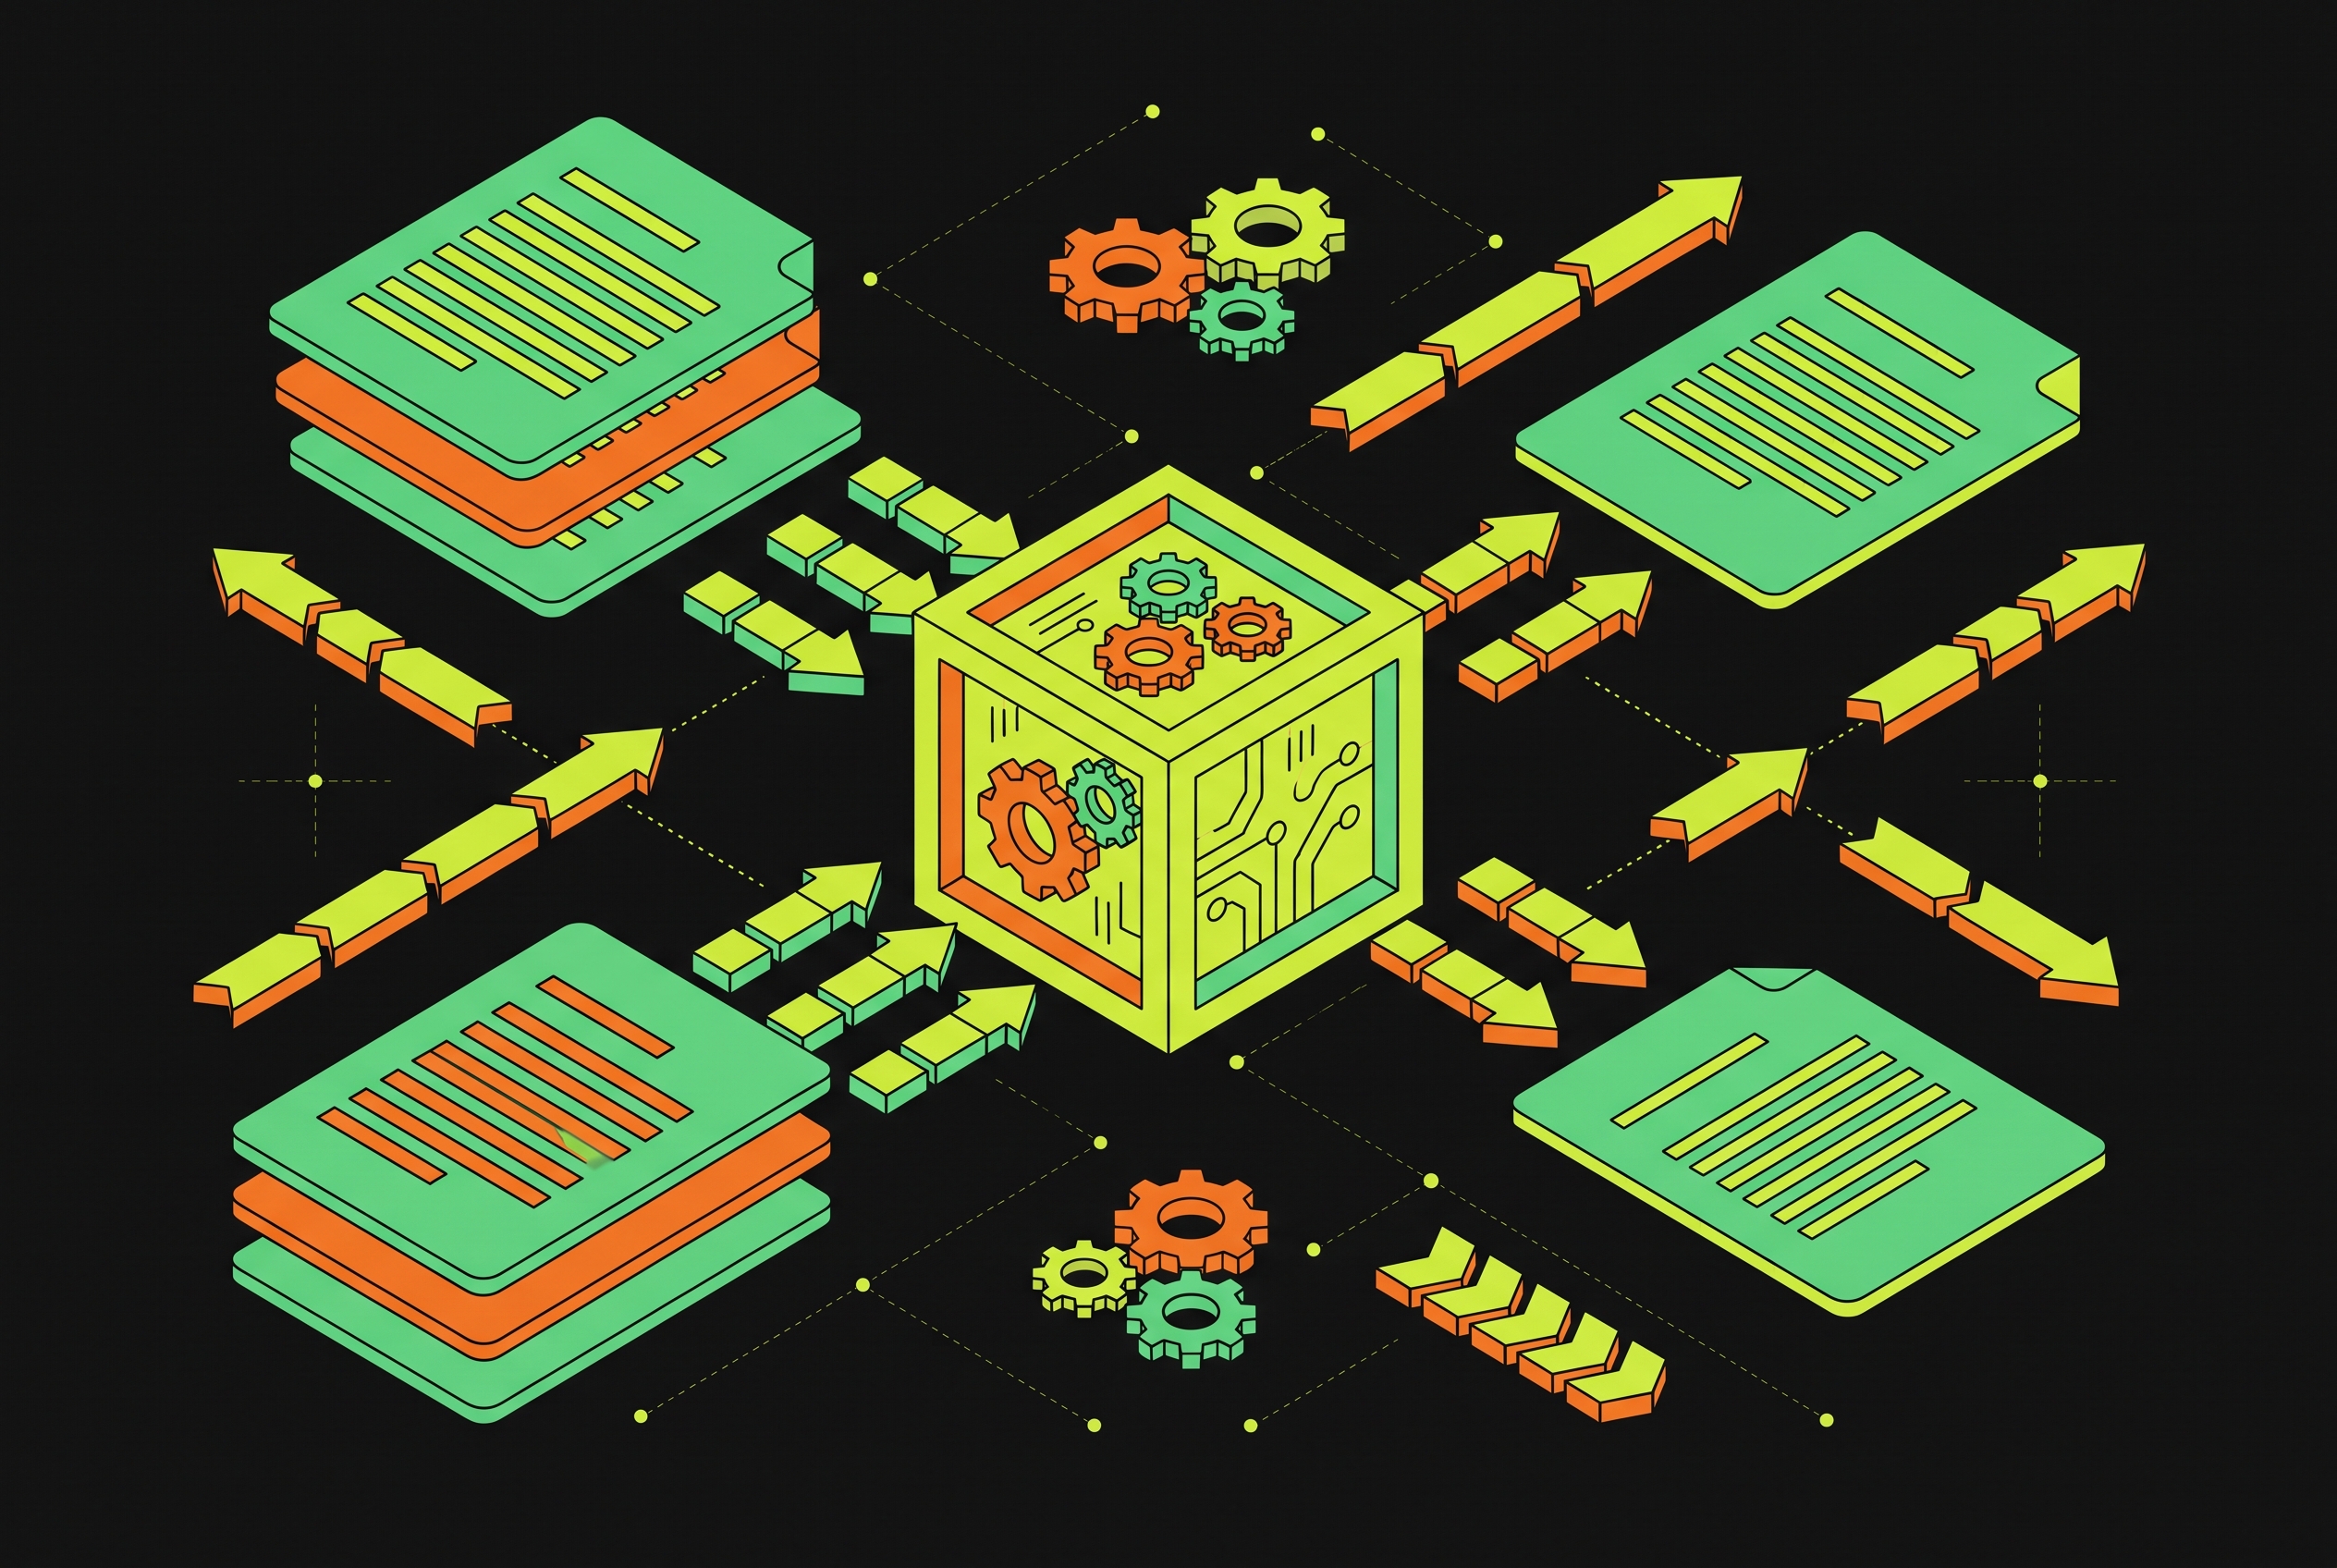
A writing kernel does for content production what a compute kernel does for hardware utilization: it takes a messy, resource-hungry problem and turns it into a deterministic, composable unit that can be tested, versioned, and improved on purpose. Engineers already know what a kernel is in the GPU sense: a unit of code that abstracts away the underlying hardware complexity, arbitrates how resources get used, and gets rewritten and re-profiled until it hits a target. That loop, write, execute, profile, refine, is the same cycle automated kernel generation research identifies as the core pattern behind agentic optimization work. Writing systems built around a single LLM prompt have none of that structure. There's no correctness gate, no resource arbitration, no refinement loop, just a call and a response. The term "writing kernel" names what's missing: the composable, deterministic core of a content production system, distinct from whatever chat interface or dashboard sits on top of it.
Writing kernels versus a single LLM prompt
A single call to a language model returns text that sounds plausible, can't be verified without a separate check, and carries no mechanism for staying on-brand once it's one of hundreds of pieces in a corpus. For a team producing a handful of pieces a month, that might be tolerable. For a team running content as infrastructure, it's a liability, because every output has to be read and corrected by a human before anyone can trust it.
Three structural problems appear in this gap, each traceable to the fact that a single prompt has no internal check on its own output. And a single model's output carries a stylistic signature, consistent word choices, sentence rhythms, structural habits, that compounds across a corpus into something that reads as machine-made even when every individual sentence is fine.
None of this is a prompt engineering problem. Lengthening the system prompt doesn't add a verification step, and it doesn't add a mechanism that checks voice against a standard. A common objection holds that fine-tuning alone fixes inconsistent voice. Fine-tuning narrows the drift, but it still leaves a single generation path with no adversarial check on what comes out of it: one model, one pass, no structural correction. That's an improvement in degree, not a change in architecture.
The four operations a writing kernel runs: draft, critique, vote, recurse
A writing kernel is a four-operation loop, draft, critique, vote, recurse, where each operation takes a defined input, produces a defined output, and has a correctness criterion attached to it. That's what makes the whole system testable: you can check each step's output against its own criterion rather than reading the final text and guessing whether it's good.
Draft is where one or more models generate candidate text, but not against a blank prompt. Generation runs against a deterministic template and a bound voice corpus, which makes it a constrained generation task. The corpus binding is what separates this step from an ordinary LLM call: strip it out, and the system defaults to generic, category-standard phrasing no matter which model is running underneath.
Critique is a separate evaluator, ideally a different model from the one that drafted, probing the draft for off-brand phrasing, factual claims with no support behind them, detectable AI filler patterns, and policy violations. A model critiquing its own output is self-referential, checking a draft against the same blind spots that produced it, and it does nothing to break the fingerprinting problem that single-model systems carry.
Vote puts a council of models in front of the candidate drafts, scoring each on defined dimensions, voice fidelity, factual groundedness, stylistic compliance, and the draft that advances is the one with consensus support, not the one a single model happened to favor. The structure mirrors how multi-agent kernel optimization workflows coordinate agents with distinct, complementary roles, where no one agent owns the final result.
Recurse sends anything that fails to clear the vote threshold back to the draft step, and the loop keeps running until the output converges, not until a clock runs out. Convergence criteria, a minimum vote score on every dimension the system defines, are what make the loop deterministic and auditable. Without them, recursion is just retrying with no standard to retry against. Running the loop multiple times lets the system reach parts of the solution space a single pass can't get to, and research on iterative kernel refinement using multi-turn reinforcement learning shows that scaling serial refinement outperforms parallel sampling for this class of problem, with iterative generation guided by execution feedback, though results vary by problem type.
Adversarial critique across multiple models fixes detectable AI output
Single-model output gets flagged as AI-generated less because of what it says and more because of how consistently it says things a particular way. Routing a draft through models with conflicting stylistic tendencies is a structural answer rather than a quality nicety, because the fix has to work at the level of how consistently output is written.
Watermarking research makes the mechanism precise. As of 2026, some AI systems embed signatures in the word choices made during generation itself, so the watermark lives in the generation path from the start. Work out of ETH Zurich's SRI Lab on durable watermarking and semantically conditioned fingerprinting shows this is an active research area with real engineering behind it, not a theoretical concern sitting in a paper somewhere.
A fair objection to watermark-based detection is that most schemes degrade sharply once the output gets paraphrased or passed through a second model. The vote step is diversification, producing text that no single model, left alone, would have written, and that mechanism stops any single model's detectable patterns from surviving into the final output. Letterwrite's writing kernels are built around exactly this property, spreading output across many models to avoid watermark exposure and single-model reliance, the architectural bet the design makes.
How corpus binding enforces voice fidelity
A voice corpus is the constraint the draft step is bound to, and without that binding, no model, regardless of its capability, holds a brand's voice steady across hundreds of runs. Language models are zero-shot generalists by default. Told to "sound like us" in a prompt, they comply for a paragraph or two and then settle back into generic web prose, because nothing in the prompt actually restricts the space of words and structures available to the model.
The practical fix starts with capturing the corpus before anything else: pulling a team's most distinctive phrases, opinions, and structural habits into a document the draft step retrieves from, rather than a prompt instruction the model reads once and drifts away from. Left unchecked, that failure mode produces sentences that sound like the brand but land in the wrong key for the subject at hand.
Fine-tuning holds voice adherence more reliably than retrieval does, but it costs more to set up and degrades when the underlying base model gets updated out from under it. The critique step catches what the draft step alone misses here too: the adversarial evaluator gets prompted specifically on what the brand does not sound like, which triggers a different kind of detection than simply asking a model to confirm the draft matches the brand.
Post-trainability: why a writing kernel that cannot learn from a team's own output is incomplete
A writing kernel that can't adapt from a team's own approved output is a one-time setup, not infrastructure, and one-time setups drift in the same way unconstrained prompts do. The distinction that matters is between a system that enforces rules fixed at configuration time and one that updates those rules from the corpus of output a team has already signed off on as correct. The second gets better from use.
This mirrors the same principle behind multi-turn reinforcement learning approaches to kernel optimization: the system improves by learning from its own execution history rather than by being reconfigured by hand each time something drifts. In a writing kernel, approved output becomes training signal, and the vote step's convergence criteria tighten as the model council learns what a team's reviewers consistently sign off on, so voice fidelity improves the more the system runs. Letterwrite's writing kernels are built to be post-trainable on a team's own corpus: the output approved today shapes what the kernel converges toward tomorrow, which makes the system specific to one team's voice rather than a generic tool applied uniformly across every customer.
A reasonable objection says this requires curating approved output, and curation is work. Teams make approval decisions on every piece of content already, whether they capture that judgment as structured training signal or let it evaporate the moment the piece gets published. A team's tools are set up to produce one of those two outcomes.
How writing kernels wire into a developer stack
A writing kernel only functions as infrastructure if every one of its capabilities can be called by an agent through an API, not only clicked through by a person in a browser tab. That puts the interface layer on equal footing with the loop architecture itself: a kernel with a flawless draft-critique-vote-recurse cycle locked behind a login screen isn't composable, and composability is why it's called a kernel.
Developers reasonably expect composable primitives that slot into a stack they already run: a CLI binary, an API endpoint, an MCP server, not a web app that demands a new account and a learning curve. Several tools already work this way. Wonda runs a full marketing pipeline as a single binary with no runtime dependencies. n8n handles workflow automation through a visual browser interface alongside CLI commands for managing instances, plus more than 400 native integrations. Sanity Agent Actions provides an API-native layer for document creation, transformation, translation, and other AI-driven content operations. A minimal but workable developer stack can run on Claude Code at its low-cost subscription tier, n8n self-hosted for free, the Groq Whisper API on its free tier, and a Notion knowledge base, with a publishing layer on top that exposes a real API or MCP server.
Letterwrite exposes its writing kernels through an API so agents can call them directly, wire them into CI pipelines, or invoke them from a terminal, the same way any other composable primitive in a developer's stack gets used. The point where this actually pays off is agent integration: the critique and vote steps can run as distinct agent roles, a generation agent paired with a performance-analysis agent, coordinated by the kernel's own orchestration layer. That's the same pattern multi-agent GPU kernel optimization workflows use, distinct agents with complementary jobs working under a shared orchestration framework, with a human defining the workflow up front rather than reviewing every line of output after the fact.
The protocol layer decides whether a writing kernel survives as infrastructure or stays a one-off tool. MCP and A2A are emerging as the standards for agent interoperability, MCP handling agent-to-tool connections and A2A handling agent-to-agent handoffs. A writing kernel that doesn't speak these protocols can't be called by other agents in a pipeline, and a tool that can't be called by other agents has no place in a stack built around agentic workflows.
Quality gates for writing output: how to test a writing kernel the same way you test code
Treating a writing kernel as infrastructure means its output needs quality gates: automated checks with pass and fail criteria that run before any piece of content moves forward, not an editor's gut sense applied after the fact. The vote step inside the loop already functions as one gate, but it operates inside the system; external gates exist to catch what that internal step misses.
Voice fidelity gets scored against a defined rubric, typically on a 1-to-5 scale across the specification's dimensions, and a score below threshold on even one dimension sends the draft back into a rework loop before it can advance. Filler pattern detection, flagging stock AI phrases a team's own test cases have identified as failure states, runs as a lint step, functioning the same way a code linter catches style violations before a build ships.
The analogy to software testing holds exactly: a writing kernel with no quality gates is a system with no tests. Standing up the full process, a voice guide, a sanctioned set of models, a CMS with version control, a named compliance reviewer, takes roughly four to six weeks based on practitioner accounts of building these systems. Letterwrite's test cases for AI filler patterns serve as a working model for this kind of automated enforcement, running the same adversarial logic externally, as a gate before publication, that already runs inside the draft-critique-vote-recurse loop itself.
The gate does more than filter bad output before it ships. Content that clears the gates and earns reviewer approval feeds back into the corpus as the team's canonical voice signal, which is the mechanism described earlier as post-training. The gate functions as a filter and, at the same time, as the data collection step that makes the next cycle through the loop sharper than the last.